Disaster Recovery Plan for Critical Operations: playbook, tests and operational runbook
When a data center becomes inaccessible, tested procedures separate recovery from business loss — this guide provides an actionable DRP for critical operations, with scenarios, RTO/RPO decision criteria, failover runbooks and a testing checklist.
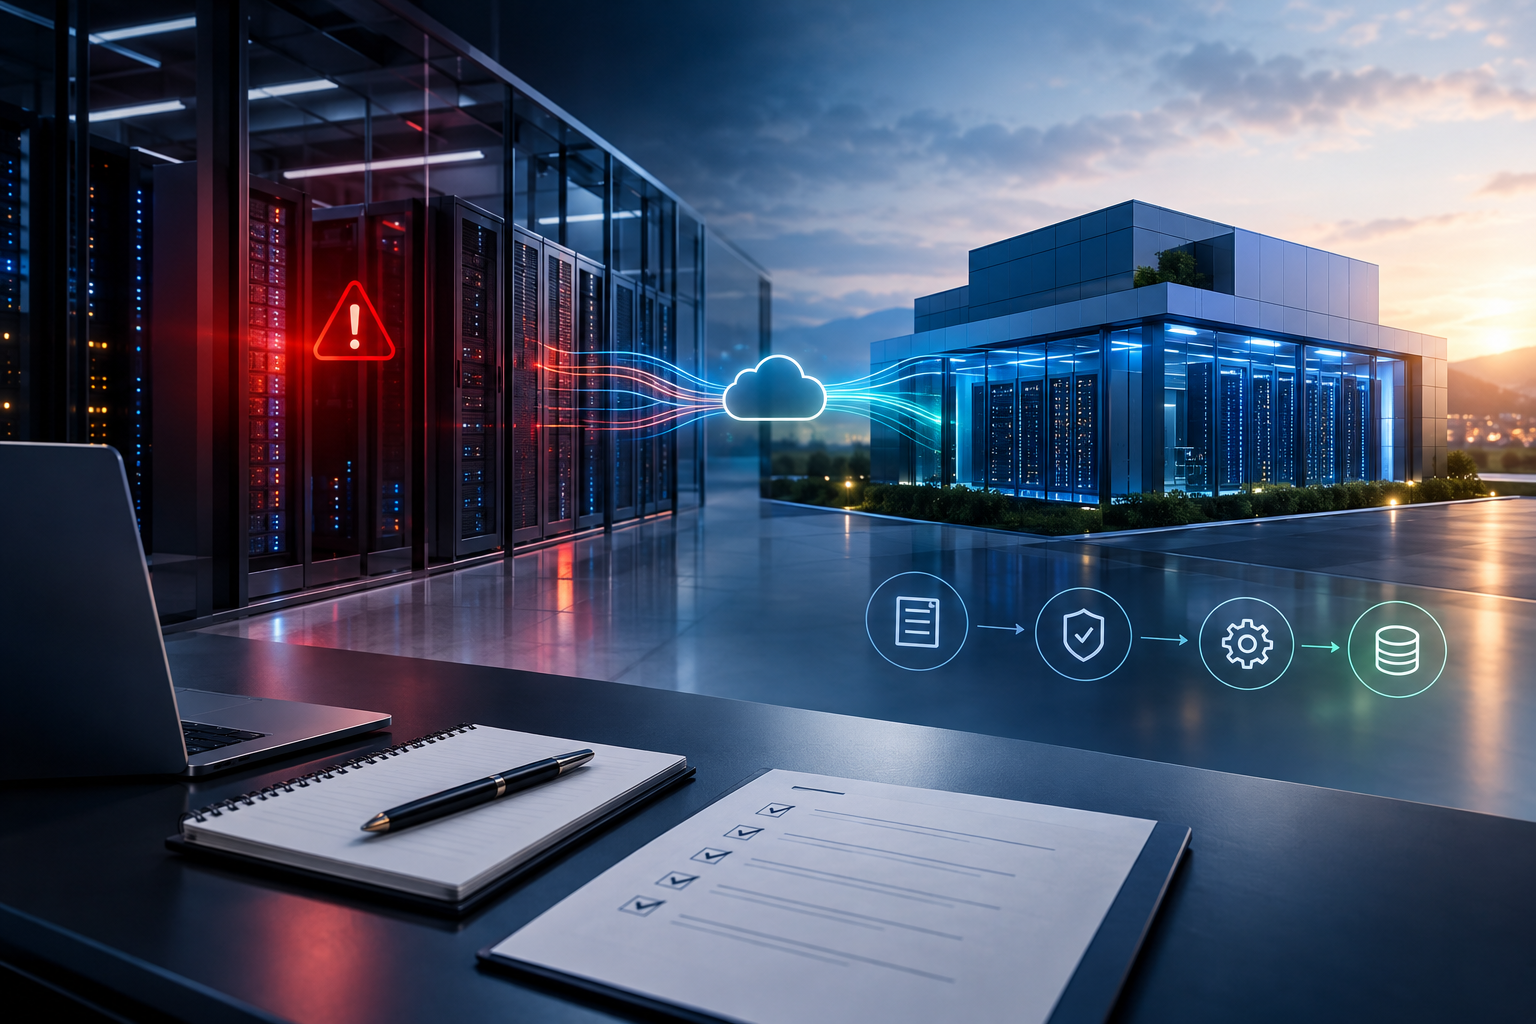
When a core data center loses connectivity or a whole site goes offline, the operational difference between recovery and prolonged loss is execution under stress: teams that follow tested playbooks bring services back predictably; teams that improvise risk extended downtime. This guide provides an actionable Disaster Recovery Plan (DRP) for critical operations — not high-level theory — including scenarios (link outage, full site failure, data corruption), practical RTO/RPO guidance, actionable runbooks and a testing calendar you can adopt now.
The central thesis: an effective DRP for critical environments aligns three concrete elements — architecture decisions (site and replication), operational playbooks, and a validated testing cadence — and only real simulations can prove readiness while preserving safety and compliance. Below you'll find minimal required components, trade-offs, decision criteria, and step-by-step procedures your team can use.
Which disruption scenarios should you prioritize?
Prioritize three scenarios that force distinct technical responses and business decisions. These are illustrative templates to validate choices:
- Link outage: loss of connectivity between clients and the primary data center or between sites; typically requires traffic reroute and partial activation of redundant services.
- Full site failure: complete unavailability of the primary site (power, facility incident) that demands secondary site activation and dependency checks.
- Data corruption or logical compromise: replicated data can also be corrupted; response needs isolation, forensic investigation and recovery from protected points (snapshots, offline backups).
Each scenario has different operational consequences: a circuit outage may allow localized failover; a site loss requires stakeholder communication and infrastructure-level failover; data corruption requires retention policies and separate recovery points. Treat these scenarios as templates for your DRP.
What are the minimum elements of a DRP for mission-critical systems?
An actionable DRP must be concise, executable and testable. Minimum elements:
- Live inventory: list of applications, dependencies (DNS, auth, third parties), critical data volumes and owners.
- Dependency map: network and service flows showing single points of failure across infra, middleware and external integrations.
- Decision criteria: thresholds that trigger DR mode (e.g., downtime beyond X minutes, integrity errors above Y%) — these must be directly linked to RTO/RPO agreed with the business.
- Scenario runbooks: step-by-step sequences with checkpoints, contacts and approval gates for secondary site activation.
- Communication plans: contact lists, templated messages for stakeholders, and procedures for internal and external communications.
- Records and evidence: logs of decisions and test results with timestamps and accountable personnel.
Without an updated inventory and dependency map, runbooks become ineffective. Update documents when architectural or vendor changes occur.
How to set RTO and RPO without guessing?
Setting RTO (Recovery Time Objective) and RPO (Recovery Point Objective) requires translating business impact into operational thresholds. Use this practical framework:
- Classify workloads by criticality (A, B, C) based on acceptable business loss: A = immediate business impact; C = limited impact.
- Match each class to maximum tolerable downtime and data loss windows through discussion with finance and product teams.
- Map incremental architecture costs for chosen RTO/RPO: site proximity, synchronous replication, extra IOPS at destination, validation operations.
- Make explicit priorities: A-tier systems often require short RTOs; evaluate whether the expense of synchronous replication and closer sites is justified.
Typical trade-off: lower RTO/RPO increases complexity and cost. For A-tier workloads, lack of investment may mean market risk. Document decisions and expected service levels.
When to choose synchronous vs asynchronous replication?
Choose based on tolerable latency, consistency and operational cost:
- Synchronous replication: ensures commit consistency between primary and secondary; suitable when data loss is unacceptable. It penalizes primary performance and requires low-latency links — increasing network and operational costs.
- Asynchronous replication: reduces impact on primary latency, supports longer distances and lower network costs; it implies an exposure window between the latest primary commit and the replica.
- Snapshots and offline backups: essential for logical corruption — replication alone may propagate corruption; keep recovery points outside the replication chain.
Practical approach: combine techniques. Use synchronous replication for transaction-critical volumes, asynchronous for less sensitive data, and snapshot retention for logical recovery.
Standard runbook: triage, isolation and secondary site activation (step-by-step)
Runbooks must be executable procedures with clear checkpoints. Below is a template flow — adapt commands and system names to your environment.
- Initial triage (0–15 min): identify scope (application, network, storage). Verify automated alerts and confirm with owners. Record timestamp and responsible person.
- Containment (15–45 min): isolate error sources to prevent spread (pause replication, isolate network segments). If corruption suspected, stop synchronization that could propagate the issue.
- Activation decision (45–90 min): compare impact to DR criteria. Obtain approval from the incident committee if policy requires.
- Activate secondary site:
- Promote endpoints and DNS routes under controlled procedure (document TTLs and update order).
- Run smoke tests to validate critical services on the secondary.
- Enable read/write capacity per architecture rules and note observed latencies.
- Operate in DR mode: run business continuity procedures; monitor performance and collect evidence for post-incident review.
- Failback planning: return to primary only after thorough validation and data synchronization; document synchronization order and reversal steps.
Each stage requires named decision-makers and pre-approved communication channels to avoid delays.
Testing checklist: tabletop to full failover
Use an incremental testing approach to limit risk and build confidence:
- Tabletop (no impact): scenario walkthrough with stakeholders to validate decisions and timelines; do this before technical tests.
- Partial failover (controlled environment): activate less-critical services on the secondary, validate replication and run smoke tests and dependency checks.
- Full failover (controlled window): switch full traffic to the secondary; requires broad communication and should follow successful partial tests.
Capture timestamps, test failures, restoration times per service and approvals in all tests. These artifacts are essential for audit and improvement.
Which metrics and checkpoints to capture in a failover runbook?
Capture metrics that prove the failover met objectives:
- Detection-to-decision latency (timestamped).
- Activation time for each critical service.
- Observed RPO (time between last consistent point and failure detection).
- Service integrity validations (automated and manual checks).
- Communication log and approvals.
Without this evidence you cannot demonstrate compliance or learn effectively.
Common testing mistakes and how to avoid them
- Testing once and assuming readiness: establish a cadence and document outcomes.
- Overlooking external dependencies: include third-party contact maps and verification steps.
- Failing to isolate logical corruption: ensure snapshots and offline backups outside the replication chain.
- Poor communication: integrate communication plans into the DRP to speed decisions.
Next steps and how MVX supports you
If you want to turn this playbook into a validated DRP for your environment, start with a diagnostic and a controlled simulation. MVX provides consultative diagnostics and technical workshops to validate your runbooks and execute failover simulations with your team. Request a DR diagnostic and workshop via /pt/contact.
For architecture choices involving hybrid replication or colocated deployments, review options in our Cloud & Edge material at /pt/solutions/cloud-edge or colocation options at /pt/solutions/colocation. Schedule a paid workshop with MVX to test specific scenarios and collect the evidence you need to operate under pressure.