Layer 7 DDoS protection: how to detect, mitigate and decide what you need
When legitimate-looking HTTP traffic crashes your app, you need a precise answer fast. This guide explains what layer 7 DDoS protection does, its limits, how to evaluate options and how to operate defenses without breaking user experience.
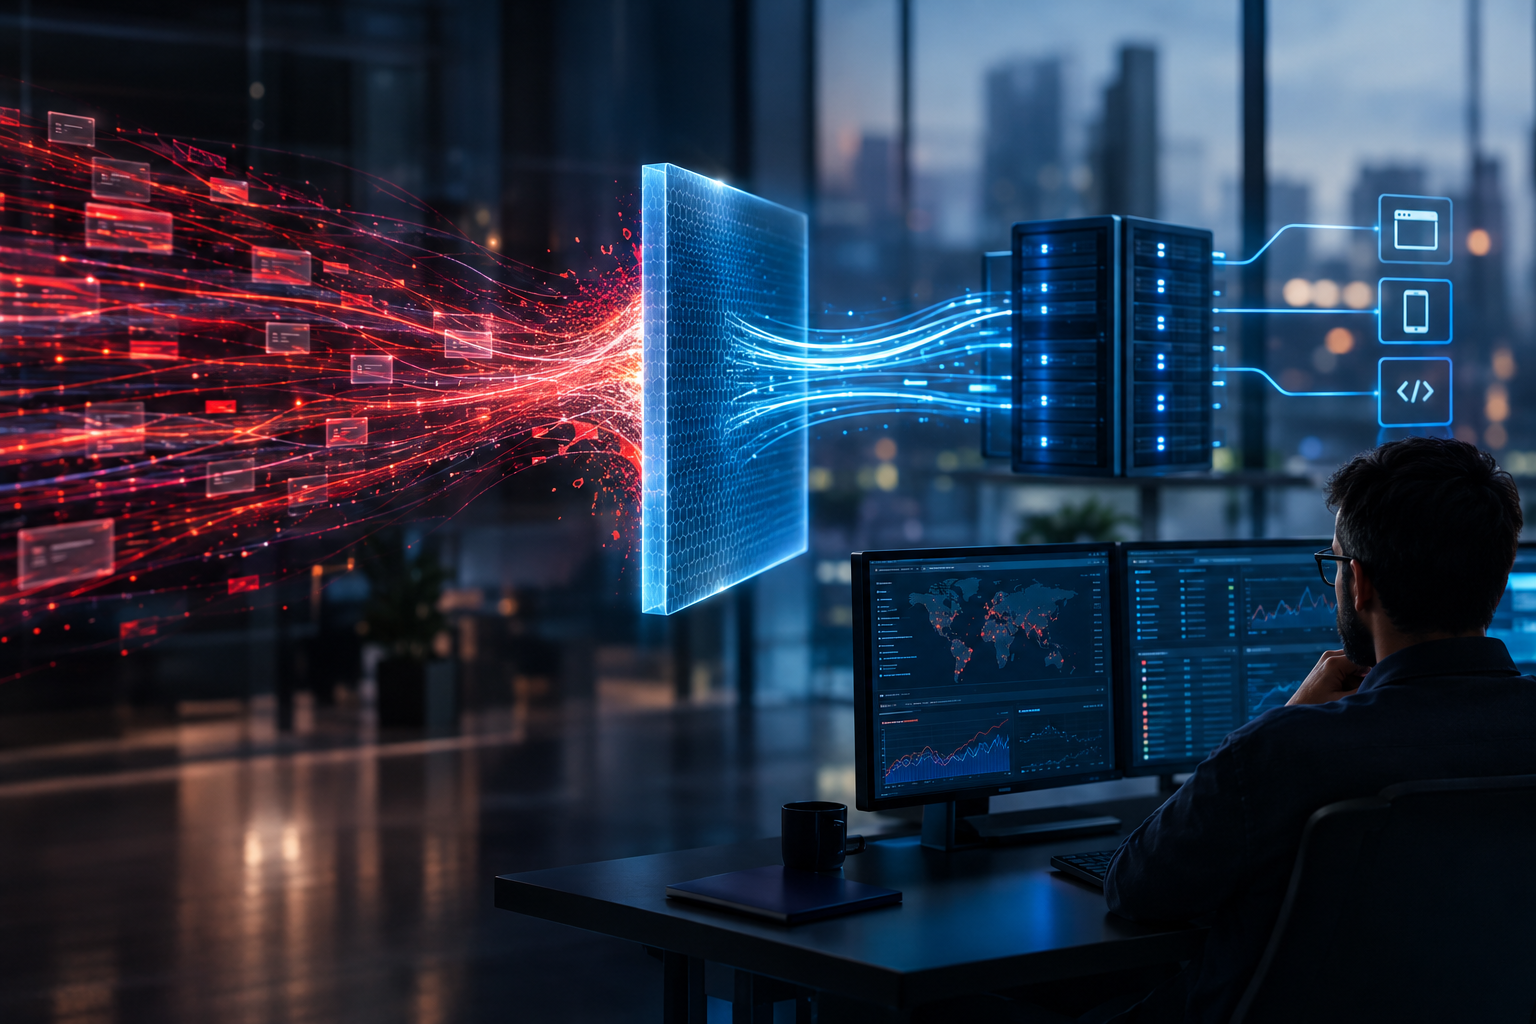
You just pushed a release and within minutes your web checkout page slows to a crawl. Metrics show tens of thousands of HTTP requests per minute coming from many IPs and user agents that look plausible. Traditional network firewalls and rate limits barely move the needle. The central question becomes: is this a layer 7 DDoS attack, and what protection will stop it without blocking real customers?
What problem does layer 7 DDoS protection solve right away?
Layer 7 DDoS protection focuses on attacks that exhaust application resources by using application-layer protocols—most often HTTP/S—to create high request volume, expensive operations (search, login, checkout) or sessions that tie up server memory and threads. The practical consequence: high application latency, failed transactions and revenue loss even when network bandwidth is ample. A good mitigation approach isolates malicious patterns at the HTTP level while preserving legitimate traffic.
Why application-layer attacks matter more today
Modern apps expose APIs, dynamic pages and complex workflows that are costly per request. Attackers exploit these characteristics: a small number of requests that trigger heavy database queries or long-lived sessions can be as damaging as massive volumetric floods. That is why defense at layer 7 must be aware of the app’s semantics, not only volumes or IPs.
Core capabilities and realistic limits
Effective layer 7 protection typically combines detection, mitigation and human review. Detection inspects request attributes and behavior; mitigation acts in near real time to block, challenge or throttle; human review evaluates ambiguous cases. But there are limits you must accept up front:
- No absolute certainty: distinguishing sophisticated automated clients from real users can require probabilistic signals. Expect false positives and negatives.
- Performance trade-offs: deeper inspection can add latency or CPU cost. Balance inspection depth against user experience.
- Coordination required: app-level rules depend on understanding endpoints and business logic; one-size-fits-all rules often break workflows.
How layer 7 mitigation works in practice
Mechanisms differ by architecture, but practical components include:
- Behavioral profiling: building a baseline of normal request rates, session characteristics and common endpoints to spot anomalies.
- Challenge-response: CAPTCHA or JavaScript challenges to separate browsers from scripts when behavior is suspicious.
- Bot and fingerprint analysis: TLS fingerprinting, header consistency checks and client-side signals to identify automated clients.
- Targeted rate limiting: per-IP, per-client, per-endpoint throttles with dynamic thresholds.
- Application-layer rules: WAF-like rules that block known malicious payloads or suspicious parameter patterns.
- Traffic scrubbing and routing: diverting suspicious traffic to dedicated pools for inspection or to scaled scrubbing services.
What these controls do not replace
Layer 7 protection is not a substitute for secure coding, capacity planning or network-layer DDoS mitigation. It complements them. For example, it will not fix a SQL injection vulnerability; a WAF rule may block exploitation attempts but developers must remediate the root cause. Similarly, a pure application-layer filter cannot absorb massive SYN floods—those require network/transport-layer defenses or upstream mitigation.
Trade-offs you will face when choosing controls
Every mitigation choice implies trade-offs that affect user experience, operational complexity and cost:
- Strict blocking vs. progressive challenge: Blocking reduces load fastest but risks blocking customers. Progressive challenge (rate limiting, CAPTCHA) is safer but slower to reduce load.
- Centralized scrubbing vs. edge filtering: Central scrubbing can be more thorough but creates backhaul and latency; edge filtering reduces load earlier but can be limited by local visibility.
- Automated response vs. human review: Automation scales and reacts fast but may misclassify novel behavior. Human review is accurate but slower.
Decision criteria: when you need layer 7 protection and what to prioritize
Use these practical criteria to decide urgency and capabilities:
- Attack surface: Do you expose public APIs, file uploads, or high-cost endpoints like search and checkout?
- Traffic patterns: Are legitimate traffic spikes common (sales, API bursts)? If yes, thresholds must be contextual to avoid false positives.
- Sensitivity to latency: Is additional millisecond latency acceptable, or do you need near-zero overhead?
- Operational maturity: Do you have an incident response runbook and staff to handle escalations?
- Integration needs: Can protection integrate with logging, SIEM, or observability stacks for forensic analysis?
Operational model: how to run protection day-to-day
Operationalize defenses with clear responsibilities and playbooks:
- Monitoring and alerting: build dashboards for request rates, error spikes, origin diversity and challenge rates. Alert on deviations from baseline, not only absolute thresholds.
- Automated mitigations: implement tiered responses: soft throttles → challenge → block. Log all decisions and allow rapid rollback.
- Change control: require staging and canarying for new rules that affect production endpoints.
- Forensic retention: keep request logs long enough for postmortem and legal review, masking PII as required.
- Periodic testing: run simulated attacks and failover drills to validate detection and escalation paths.
Example operational playbook (conceptual)
- Detect anomaly: automated alert when a key endpoint exceeds baseline by X%.
- Apply soft throttle: reduce requests per origin by 20% and monitor customer impact for 5 minutes.
- Elevate to challenge: issue browser challenges to unverified clients for next 10 minutes.
- Escalate to block and notify incident response if load persists or costs mount.
- Post-incident: review logs, tune rules, and update canary settings.
How to evaluate vendors and solutions without being misled
Ask specific, testable questions and request trial runs against realistic scenarios:
- Can the solution apply per-endpoint policies and integrate with your auth model?
- How does it identify bots and what signals are used (TLS fingerprint, JS execution, IP reputation)?
- What is the expected additional latency for an average request under normal load and under inspection?
- Can you simulate attacks in a test environment and measure false positive/negative rates?
- How are mitigations logged and how quickly can rules be changed or rolled back?
Testing and validation: practical steps
Validation is non-negotiable. Use these methods:
- Load tests with behavioral variety: not only volume but scripted sessions that mimic login, search and API workflows.
- Adversary emulation: run red-team scenarios that try to blend with legitimate traffic patterns.
- Canary rules: deploy new rules to a small percentage of traffic and analyze business metrics before wide rollout.
- Continuous tuning: update baselines weekly or after major feature launches.
Frequently asked questions
Will layer 7 protection stop all DDoS attacks?
No. It is effective against application-layer attacks that exploit HTTP/S endpoints, but it does not replace network-layer protections required for SYN floods or massive volumetric attacks. A layered defense approach is essential.
Does it increase latency for end users?
Some inspection adds overhead. The goal is to limit latency for legitimate users while applying deeper checks to suspicious sessions. Proper tuning and edge-based filtering minimize impact.
How do I avoid blocking my own customers during peak events?
Use adaptive thresholds, user-aware rules (whitelisting authenticated sessions or known partners), and canary deployments for new rules. Monitoring business KPIs during mitigations prevents collateral damage.
When to bring in external help
If you lack capacity to instrument detailed baselines, run realistic attack simulations, or operate 24/7 mitigations, consider engaging external specialists. External teams can accelerate incident response, conduct forensic analysis and help build repeatable playbooks. If you want to discuss options or arrange a technical review, you can contact Shield for an exploratory conversation at the company website.
Next step you can take today
Run a focused checklist this week: identify your high-cost endpoints, capture a one-week baseline of request characteristics, and schedule a two-hour simulation that mimics both legitimate surges and abusive behaviors. Use the outcomes to define three tiered mitigations (soft, challenge, block) and a rollback plan. If you prefer guided support, reach out to Shield to coordinate an assessment or tabletop exercise; mention the findings from your baseline so the conversation is specific and actionable.