Building a complete AI system: host, send and secure with MVX
Operational guide to design, host, promote and secure an AI-driven system—practical steps to use MVX, MVX Send, MVX Digital and MVX Shield in your delivery pipeline.
You have a working AI prototype that solves a real workflow—say, automated ticket triage or personalized recommendations—and now must put it into production without breaking performance, privacy or budget constraints. If the live system experiences latency spikes, data leaks or scaling failures, users lose trust and costs surge. This article outlines a concrete operational path: how to design the AI product, where to host with MVX, how to coordinate communications with MVX Send, when to engage MVX Digital for reinforcement, and how MVX Shield can help reduce security and availability risks.
Start by defining the outcome in one measurable sentence (for example: reduce response time by X%, increase conversion by Y points, automate Z tasks per day). Identify required datasets, minimum data quality, and production success metrics. Only after these decisions should you choose architecture and infrastructure—this prevents overbuilding and keeps focus on the business impact.
How to structure an AI product for production
Practical production architecture separates ingestion and data preparation, training/validation, inference engineering (prediction services), and operations (monitoring, rollback, audit). For each layer specify data types, update windows, latency targets, cost per request and observability needs. Set internal SLAs early (for example: 99.5% availability for critical endpoints) so infrastructure choices and redundancy planning follow directly from requirements.
Key trade-offs to document
Latency vs. cost: keeping models resident in memory lowers latency but raises costs; caching and hybrid on-demand strategies offer compromises. Accuracy vs. interpretability: complex models may perform better but require explainability. Data minimization reduces risk but may remove predictive signal. Document these trade-offs and prioritize them with stakeholders to avoid surprise decisions later.
Hosting requirements for AI workloads
Your hosting must allow autoscaling for inference endpoints, support GPU/CPU configurations for training and inference, provide environment isolation and clear backup/disaster recovery processes. Integration with CI/CD for model deployments and safe rollback procedures is vital. For high-criticality systems, add canary testing and staged rollouts before promoting a model to full traffic.
When to pick a managed provider
If your team lacks operational depth, a provider that consolidates hosting, networking and delivery speeds operationalization and lowers people costs. Managed hosting does not remove the need for governance, testing and data accountability—you remain responsible for model behavior and compliance.
Promoting the system and driving adoption
Good product alone won’t ensure adoption. Start with targeted rollouts to pilot groups, use notifications and emails to communicate changes, and run controlled experiments (A/B tests) to validate conversion hypotheses. Personalized messaging, delivered respecting privacy rules, increases adoption and reduces churn.
Benefits of a unified send platform
Coordinating multi-channel communications requires centralized templates, delivery queues and metrics. A unified service simplifies measurement and automation. If you need operational support to plan or execute campaigns, external specialists can accelerate outcomes.
Protecting data, models and apps—practical controls
Security for AI systems includes restricting access to training data, encrypting data in transit and at rest, validating inputs to prevent injection, and monitoring for anomalies indicating data poisoning or adversarial attacks. Adopt retention and anonymization policies suited to your regulatory context. Remember: technical controls work best when paired with processes and clear accountability within the team.
What security solutions won’t replace
Technical protections reduce risk but do not substitute governance, adversarial testing and human oversight. A security layer is one element of a broader resilience strategy; without review processes and incident response plans, vulnerabilities persist.
Decision criteria for hosting, sending and protecting
Use these six practical criteria: latency requirements, need for GPU resources, compliance and privacy constraints, total cost of ownership, ease of integration with your CI/CD pipeline, and operational support capability. Evaluate providers against these criteria using realistic workload scenarios rather than hypothetical benchmarks.
Application scenarios and suggested architecture
Scenario A—prototype to product: separate production data from training, use on-demand infrastructure and intensive observation during initial weeks. Scenario B—steady high-traffic service: implement multi-zone redundancy, failover testing, and strict rollback rules. Scenario C—regulated product: prioritize immutable audit logs and approval workflows for model changes.
Operational FAQ
How do I know a model remains reliable in production?
Monitor performance metrics (distribution drift, accuracy decay), inspect inference logs, set threshold alerts and run periodic labeled evaluations. Implement automatic rollback policies for versions breaching thresholds.
When should I bring external specialists?
Engage specialists for scaling infrastructure, campaign optimization, or security audits when internal capacity cannot meet delivery timelines, or when you need a targeted uplift in expertise.
Where MVX fits into your delivery flow
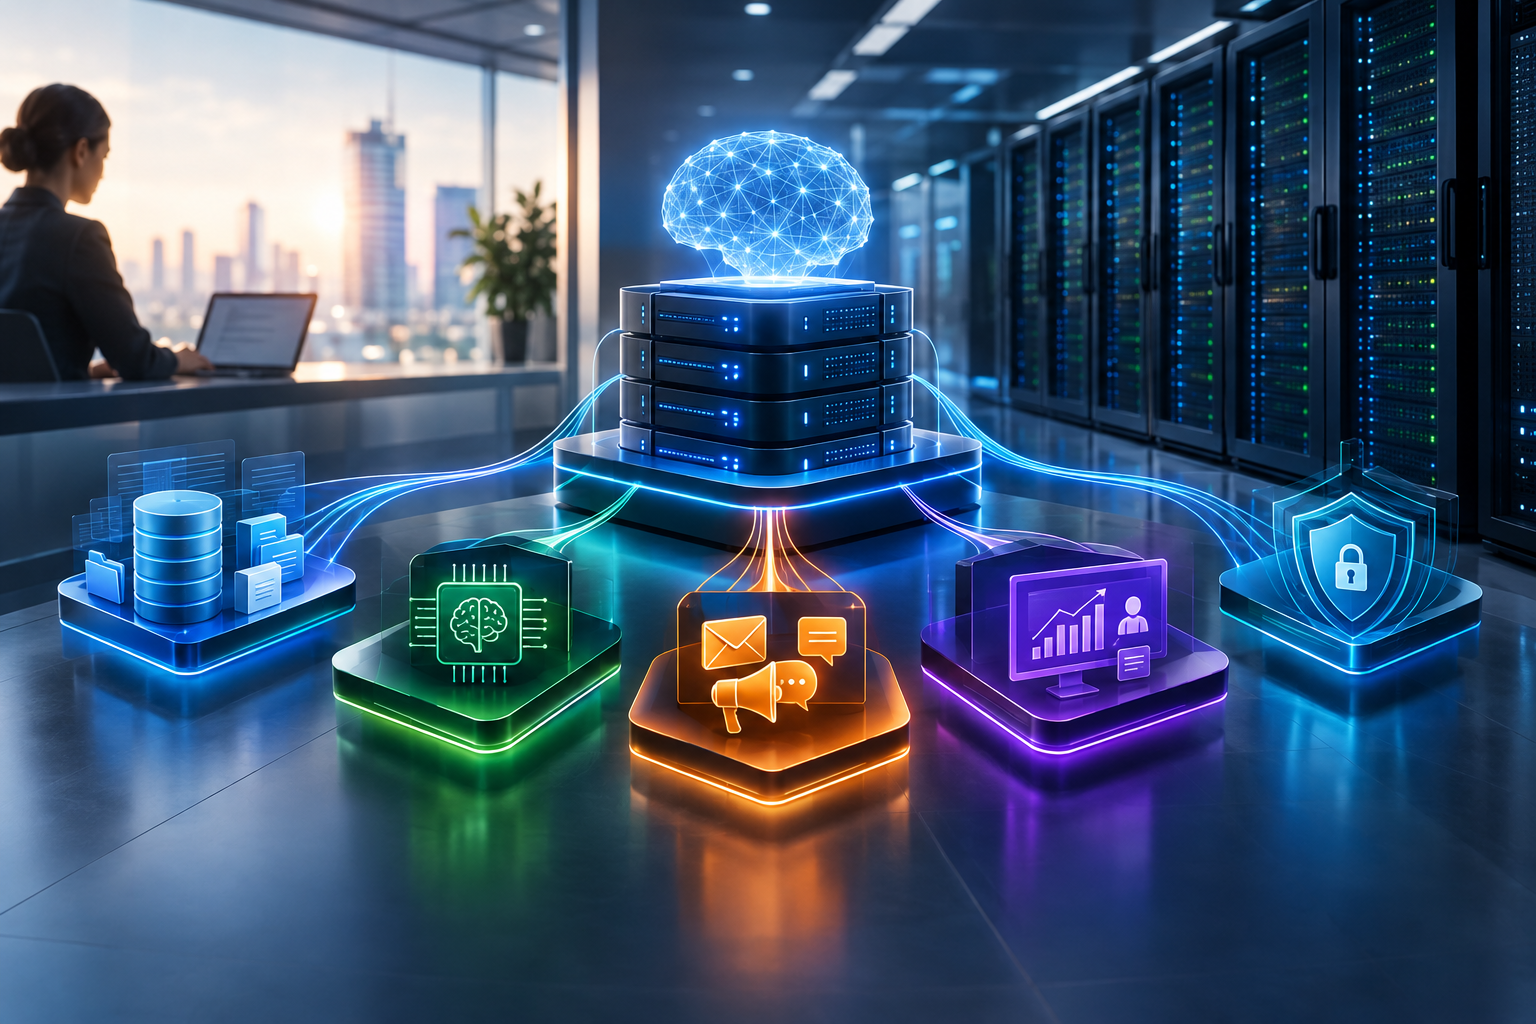
Once architecture and requirements are set, consider hosting APIs and applications with MVX to centralize infrastructure needs. Use MVX Send to orchestrate communications. If you require support for campaign execution or digital strategy, involve MVX Digital. To strengthen security and availability layers, adopt MVX Shield. These are operational touchpoints that can reduce friction across engineering, operations and marketing teams.
Suggested operational roadmap
- Weeks 0–2: define business outcome, metrics and data requirements.
- Weeks 3–6: prototype inference and test with sample datasets.
- Weeks 7–10: deploy to controlled environment, integrate CI/CD, run load and security tests.
- Weeks 11–14: pilot launch, measure KPIs, iterate.
- Week 15+: gradual scale, use MVX Send for communications and MVX Digital for campaign support.
Metrics to monitor post-launch
Track median and p95 latency, error rates by endpoint, cost per thousand inferences, message delivery success, mean time to recovery (MTTR) and security incident counts. Correlate infrastructure metrics with business KPIs to evaluate cost-effectiveness.
Final checklist before going live
- Single measurable success metric for the first quarter.
- Classification of sensitive data and protection plan.
- Rollback authority and trigger criteria.
- Owner for experimentation and communication channels.
Practical next step
If you have a prototype and want to move to production with integrated hosting, sending and security, request a technical assessment. Describe your latency and compliance needs and share current metrics for an initial readiness review. Visit the MVX site to explore hosting and operational support and schedule an evaluation.
Explore MVX and request a technical assessment to adapt this plan to your context.